How to Use an Old PC for Local AI (Single PC vs. RAMDeck Cluster Pooling)
To use an old PC for local AI, you have two approaches depending on your hardware goals:
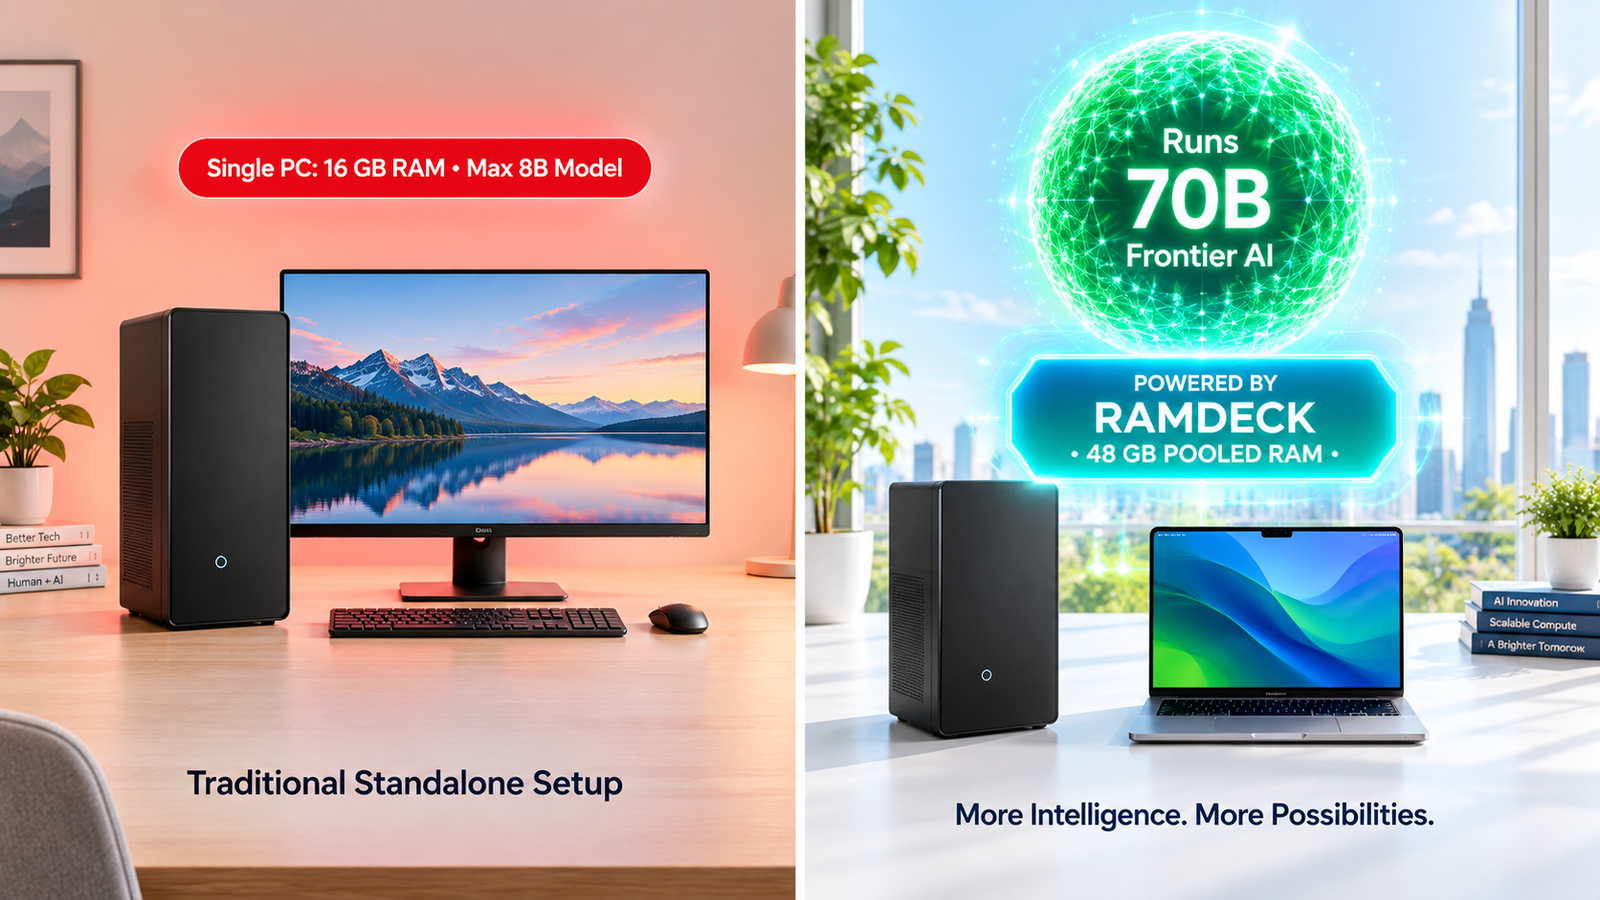
- Single-PC Mode (Small Models): If running one isolated machine with 8 GB to 16 GB of RAM, tools like LM Studio or Ollama let you run compact 3B to 8B parameter models on your CPU. However, a single machine is strictly bounded by its motherboard memory ceiling.
- Multi-PC Pooling with RAMDeck (Recommended): Instead of settling for small models, RAMDeck connects your old PC to another desktop, laptop, or Mac over your local network to pool their physical RAM. Pairing two ordinary 16 GB computers provides a 26 GB+ usable memory pool that runs frontier 14B, 30B MoE, and 32B coding models without buying a new graphics card.
The Single-PC Limitation: Why You Hit the Memory Wall
The most common misconception in local AI is that older computers lack the processing power to run modern open-source models. In reality, modern x86 computer processors equipped with AVX2 or AVX-512 instructions are capable matrix calculators.
The true bottleneck is memory capacity. A modern, highly capable model like Qwen 2.5 32B or Llama 3.3 70B requires between 20 GB and 42 GB of RAM just to hold its weights. An older laptop or desktop with 8 GB or 16 GB of RAM will experience an Out-of-Memory (OOM) crash or crawl into disk swap.
Hardware Comparison: Single Old PC vs. RAMDeck Clustered Setup
Below is how model capability scales when you use an old PC alone versus networking it into a RAMDeck cluster:
| Old PC Setup | Available AI Memory | Max Model Size | Real-World Generation Speed | Tool Required |
|---|---|---|---|---|
| Single Old PC (8 GB RAM) | ~5 GB usable | 3B Models (Llama 3.2 3B, Qwen 2.5 3B) | 8 – 15 tok/s (CPU) | LM Studio / Ollama |
| Single Old PC (16 GB RAM) | ~12 GB usable | 7B – 8B Models (Llama 3.1 8B) | 5 – 9 tok/s (CPU) | LM Studio / Ollama |
| Two Old PCs Pooled (2x 16 GB) | 26 GB usable | 30B MoE & 32B Dense Models | 12 – 38 tok/s (Pooled) | RAMDeck |
| Three Consumer Devices Pooled | 42 GB usable | Full 70B Frontier Models | 1.8 – 2.5 tok/s (Continuous) | RAMDeck |
Can LM Studio or Ollama Combine RAM From Multiple Computers?
To pool memory across multiple computers, you need an orchestration layer like RAMDeck. It runs a lightweight node agent on each computer, partitions the neural network’s layers sequentially across your devices, and routes intermediate activation vectors over your home network.
Why Network Bandwidth Doesn’t Choke Inference Speed
A common concern among engineers is whether sending data over local Wi-Fi or Ethernet slows down token generation.
The answer is no: In distributed pipeline inference, the heavy weight matrices are loaded once into each computer’s memory during boot and remain permanently resident in RAM. During token generation, nodes only pass compact intermediate activation vectors (~4 KB to 16 KB) between one another.
Over standard Gigabit Ethernet (125 MB/s), transferring a 16 KB activation vector takes just 0.13 milliseconds—less than 1% of the compute cycle per token. In our live benchmarks, pairing a budget mini PC with an older laptop ran a 30B Mixture-of-Experts model at 38 to 39 tokens per second (see live video benchmarks).
Watch an Aging 2019 Laptop Host a 40B Parameter Model
Explore the Complete Multi-PC Setup Guides
Ready to network your machines? Follow our step-by-step tutorial: How to Run an LLM Across Multiple Computers Without a GPU. If one of your computers runs Linux, read How to Run an LLM on Linux.
Frequently Asked Questions
Can I use an old PC for local AI without a dedicated GPU?
Yes. Modern CPUs support AVX2 instruction sets that can evaluate quantized models directly in system RAM. While single machines are limited to small 3B to 8B models, pooling multiple older computers with RAMDeck enables you to run 32B and 70B models at conversational speeds without dedicated graphics cards.
Can LM Studio combine RAM across two computers?
No. LM Studio can only access the physical RAM and GPU inside the single computer where it is installed. To pool memory from two separate computers over your local network, you need a distributed inference layer like RAMDeck.
How much RAM does an old PC need to run an AI model?
For standalone execution, an old PC needs at least 8 GB of RAM to run lightweight 3B models, or 16 GB of RAM for 7B–8B models. By connecting two or more machines with RAMDeck, their memory is combined into a single virtual pool (e.g., two 16 GB PCs provide 26 GB usable memory for 32B models).
Can I mix a Windows PC with a Mac or Linux laptop?
Yes. RAMDeck’s cross-platform RPC architecture connects Windows (CUDA/CPU), macOS (Metal Apple Silicon and Intel CPUs), Linux (Ubuntu/Debian), and mobile devices into a single unified cluster over standard TCP/IP.